Your AI assistant gives you a confident answer. It sounds right. Then you check it and find it made up half the details.
That is the hallucination problem. And RAG – Retrieval-Augmented Generation is the most practical fix the industry has found so far.
Here is what it actually is, why it matters, and how you can use it without a PhD in machine learning.
What Is RAG?
RAG stands for Retrieval-Augmented Generation. It is a technique that gives a language model access to external information at the moment it answers a question.
Standard LLMs only know what was in their training data. Ask about last week’s news and they either guess or refuse. RAG solves this by adding a retrieval step before generation.
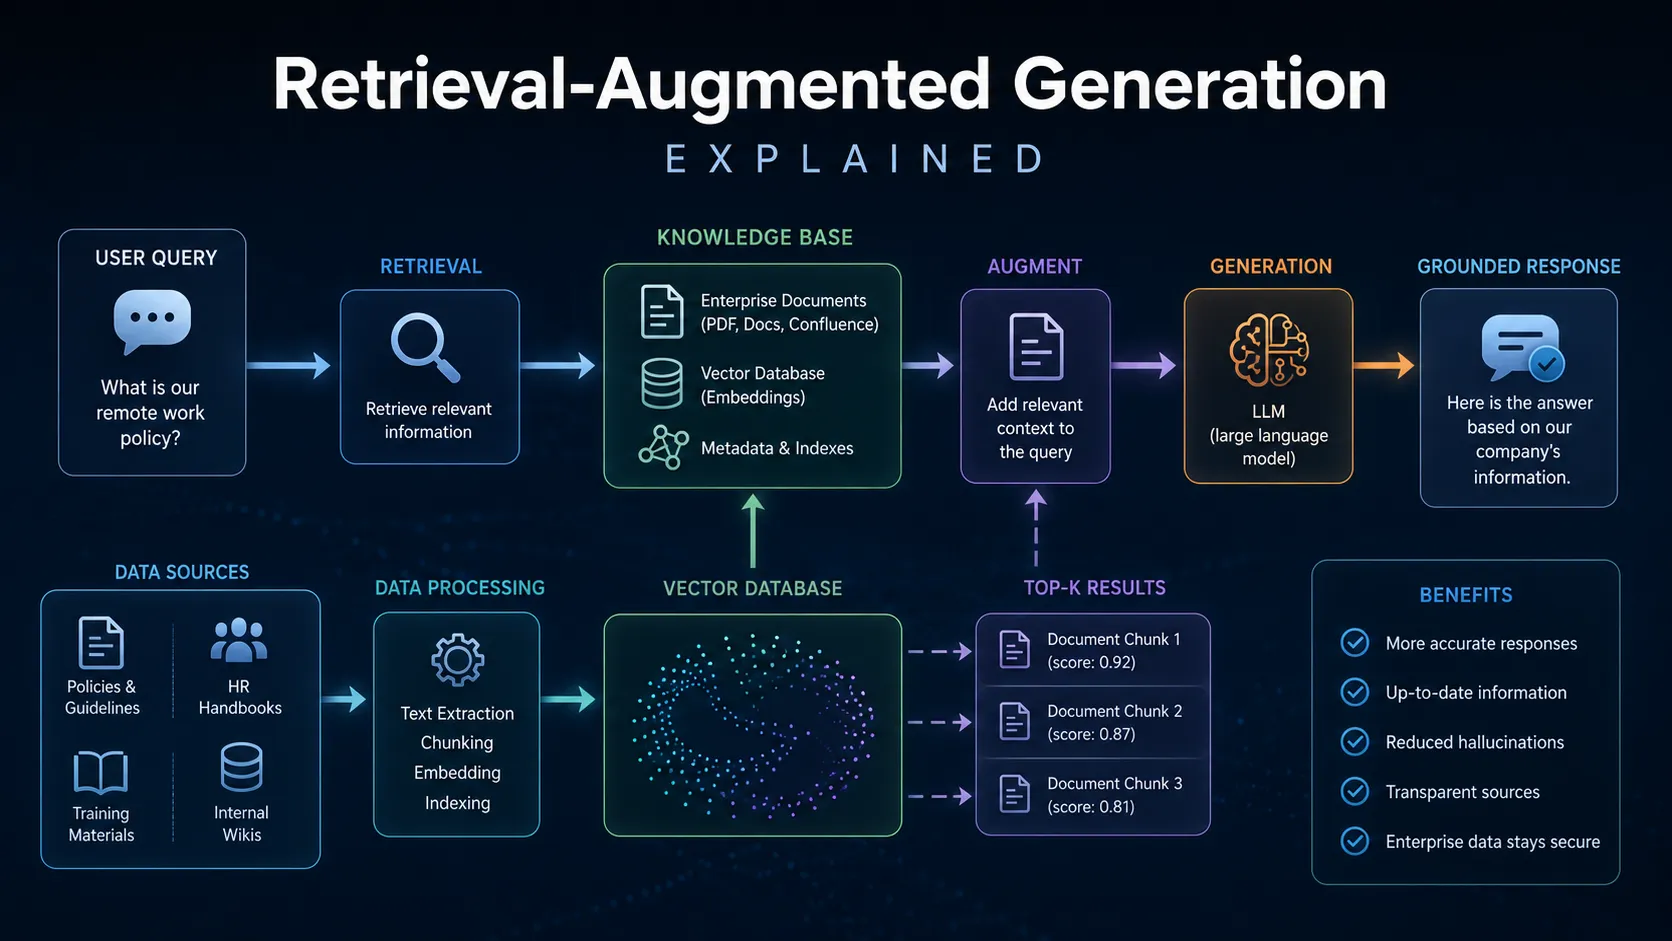
When you ask a RAG-powered system a question, three things happen in sequence:
- Retrieve: The system searches a knowledge base for documents relevant to your question.
- Augment: Those documents get inserted into the prompt alongside your question.
- Generate: The model reads both and produces an answer grounded in the retrieved material.
The result is an AI that can cite sources, stay current, and work with your private data, without being retrained from scratch.
Why RAG Matters in 2026
Enterprise AI has moved from experimentation to production. That shift created a hard requirement: the model must be trustworthy, not just impressive.
RAG is the dominant architecture for enterprise AI in 2026 because it lets companies connect LLMs to proprietary data, internal wikis, customer support tickets, legal documents, and product catalogs without retraining or fine-tuning the model.
This matters for three reasons:
- Answers stay current. Your knowledge base updates; the model stays fresh automatically.
- Every claim traces back to a source document. Auditors and compliance teams can verify outputs.
- Hallucinations drop sharply. When the model has relevant context in front of it, it fabricates far less.
How RAG Actually Works: The Technical Bit
Most RAG systems use embeddings to match questions to documents. Here is the process broken down:
Step 1: Indexing
Your documents get split into chunks and converted into vector embeddings, numerical representations of meaning. These go into a vector database.
Step 2: Retrieval
Your question also becomes an embedding. The system finds the document chunks whose embeddings are closest to your question’s embedding. Closest in mathematical space means closest in meaning.
Step 3: Augmentation and Generation
The top chunks get pasted into the prompt. The model sees your question plus the retrieved context and writes its answer using both.
RAG vs Fine-Tuning: Which Should You Use?
| Factor | RAG | Fine-Tuning |
| Knowledge update | Instant – change the database | Requires full retraining |
| Cost | Low – retrieval at query time | High GPU hours at training time |
| Auditability | Yes – sources are traceable | No – knowledge baked in weights |
| Best for | Current, proprietary data | Consistent tone, domain behavior |
| Hallucination risk | Lower when context is relevant | Higher for facts outside the training set |
The short answer: use RAG when you need your AI to know things that change. Use fine-tuning when you need your AI to act a certain way. Most production systems in 2026 combine both.
Advanced RAG Patterns You Should Know
Basic RAG works. Advanced patterns work better.
- Agentic RAG: Multiple specialized agents handle query decomposition, retrieval, validation, and synthesis in parallel. This is the dominant enterprise pattern in 2026.
- Self-reflective RAG: The model evaluates its own retrievals and re-queries when evidence is weak. This cuts hallucinations in high-stakes domains.
- RAFT: Retrieval-augmented fine-tuning combines both techniques. You train the model to reason over retrieved documents in a domain-specific way.
- Graph RAG: Instead of flat vector search, a graph database captures relationships between entities. Better for complex reasoning that spans multiple documents.
Common RAG Failure Modes (And How to Avoid Them)
RAG is not perfect. These are the problems practitioners hit most often:
- Lost in the middle: If you stuff too many retrieved chunks into context, the model loses track of the most relevant ones. Fix: limit chunks, use reranking.
- Retrieval-generation misalignment: The retriever finds something relevant; the generator ignores it and goes rogue. Fix: co-design and evaluate both components together.
- Security bypass: Flat vector stores with weak access control can expose content to users who should not see it. Fix: Enforce the same permissions as source systems.
- Lexical mismatch: The user phrases a question differently from how the document phrases the answer. Fix: use hybrid search combining semantic and keyword methods.
Real-World RAG Use Cases
| Industry | Use Case | Why RAG Fits |
| Legal | Contract review and clause lookup | Firms cannot retrain a model on every new case file |
| Healthcare | Medical Q&A grounded in clinical guidelines | Guidelines change; hallucinations are dangerous |
| Customer Support | Answer questions using product documentation | Documentation updates constantly |
| Finance | Research assistant using earnings reports | Regulatory data is highly specific and time-sensitive |
| HR | Policy questions answered from employee handbook | Private data that cannot be sent to a public model |
How to Build a Simple RAG System
You do not need a machine learning team to get started. Here is a practical path:
- Choose a vector database: Pinecone, Weaviate, Qdrant, or Chroma, all work.
- Choose an embedding model: OpenAI’s text-embedding-3-small is cost-effective. Voyage AI and Cohere offer strong alternatives.
- Chunk your documents: 512-token chunks with 50-token overlap is a solid starting default.
- Build the retrieval pipeline: Top-k retrieval with a reranker like Cohere Rerank improves precision.
- Wrap with an LLM: GPT-4o, Claude, or Gemini 1.5 Pro all handle long retrieved contexts well.
Open-source frameworks like LangChain, LlamaIndex, and Haystack provide pre-built RAG pipelines that cut months of work to days.